Writing
Notes on proving software works
False greens, the agent dev loop, and what it takes to trust a green check.
The Jev playbook: where it wins, where it lags, and the number behind each call
Eleven workloads, and whether TypeSafe AI's Jev should take them. Every verdict carries a measured number, from our own harness and from the people who shipped on it first.
Read → Guide · September 19, 2026 · 11 min read
Which decisions in your testing agent should be Jev calls
A practical guide to wiring TypeSafe AI's Jev into a testing agent: Choice, Score and Noul question design, option sets, batching, and what must stay in code.
 Engineering · September 19, 2026 · 9 min read
Six things TypeSafe AI's Jev cannot do, and the one that will cost you a release
TypeSafe AI's Jev cannot abstain, explain itself or read your field names, and holds 32K. A field guide to the System One model's limits and which ones hurt.
 Benchmarks · September 19, 2026 · 9 min read
Jev works. The question is whether the giants let it live.
TypeSafe AI's Jev drove our verification harness for $0.006 and found a 100x under-refund that a green Playwright suite walked past. It is a real breakthrough. Netscape was a real breakthrough too.
 Benchmarks · September 19, 2026 · 8 min read
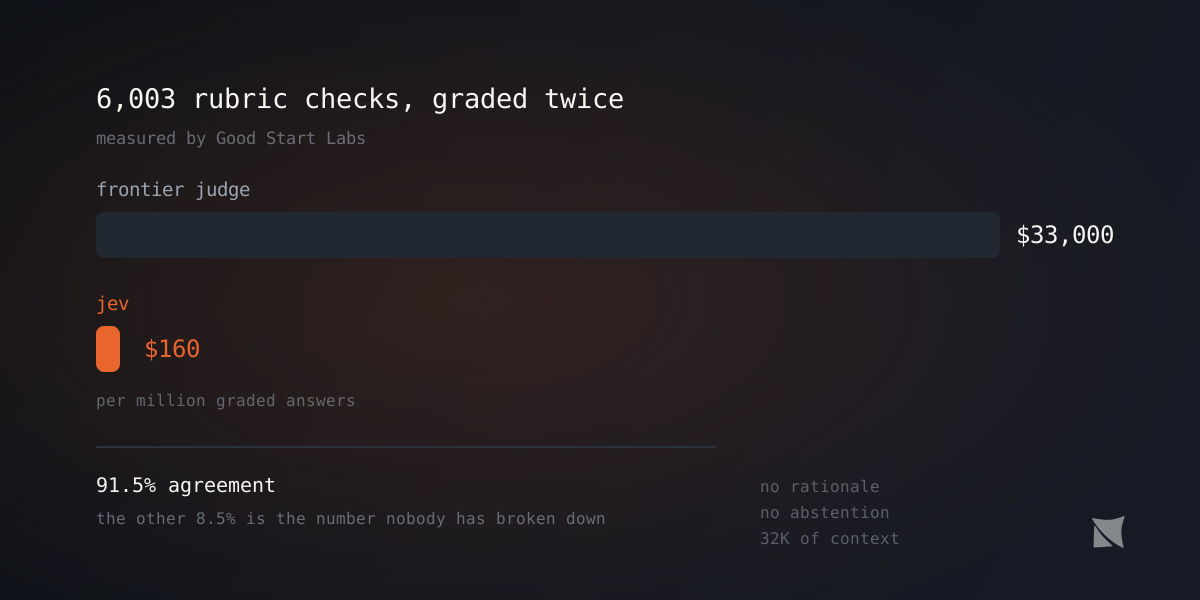
Jev vs LLM-as-judge: what $160 per million graded answers actually buys
Jev matched a frontier judge 91.5% of the time at $160 per million graded answers against $33,000. What a System One model changes about evals, and what it cannot.
 Story · August 30, 2026 · 8 min read
Reticle started because I was too lazy to stay awake
Half a Claude Code quota, one night of sleep, and a morning that looked like a car crash. How a batch of wasted tokens turned into a product people queued up to install.
 Guide · August 29, 2026 · 7 min read
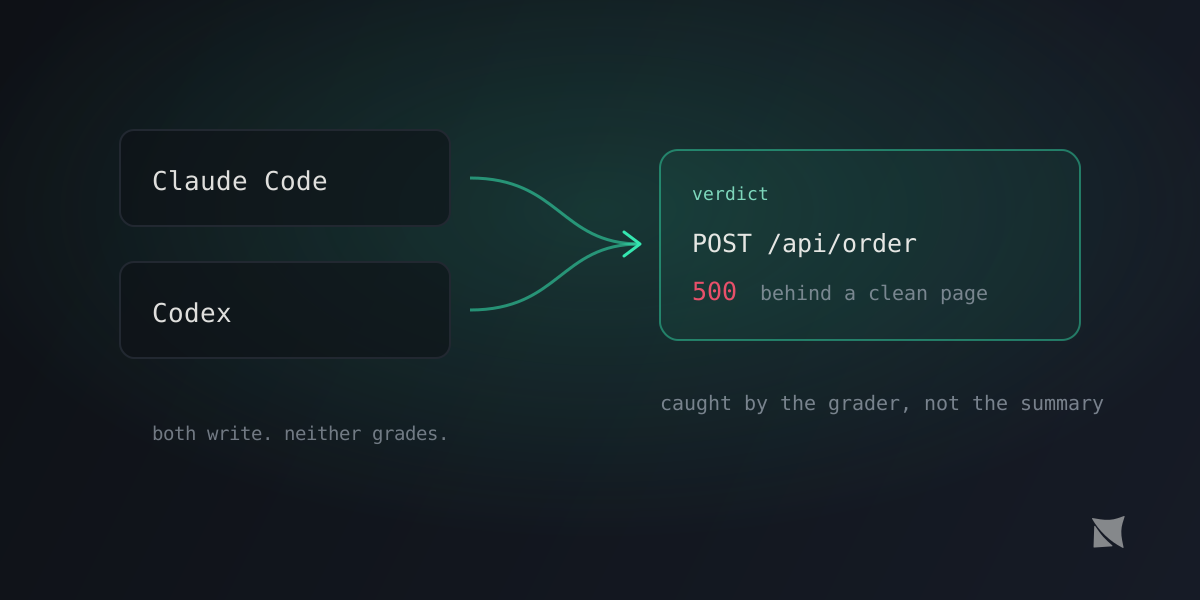
How to use Claude Code and Codex for testing
A working setup for testing with coding agents: what to hand them, what to never let them decide, and how to stop believing a summary that says everything passes.
 Guide · August 7, 2026 · 5 min read
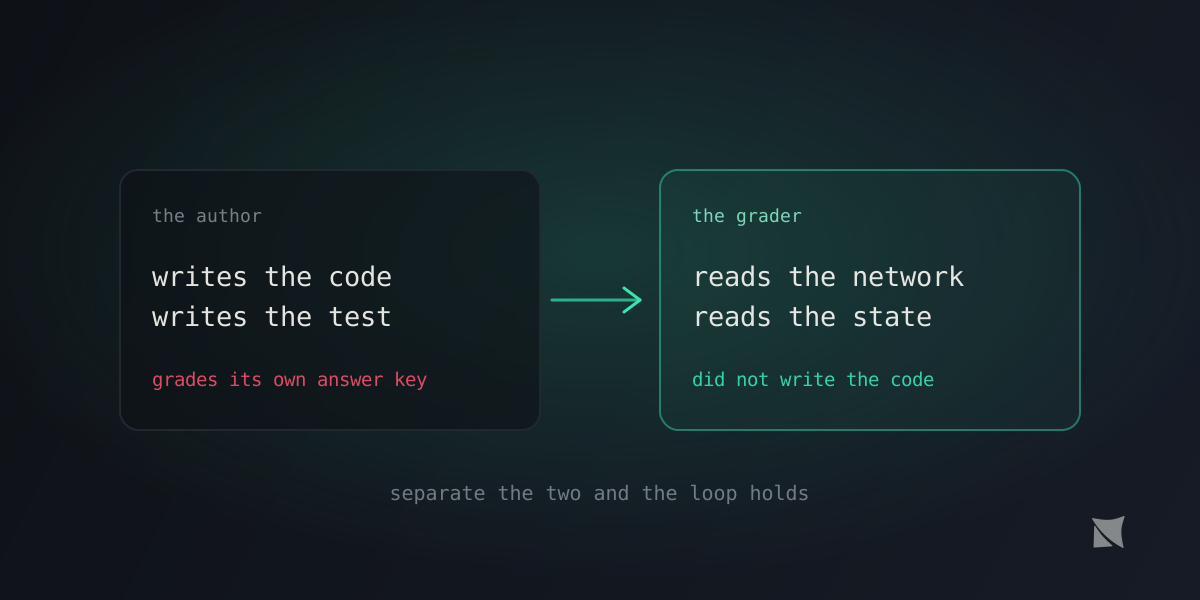
How to use Claude Code for QA automation
A practical setup for making Claude Code test its own work: what it can verify on its own, where it quietly fails, and how to give it a check it cannot fake.
 Engineering · June 24, 2026 · 2 min read
Why a green check isn't proof
A passing test tells you the page rendered. It doesn't tell you the app works. The gap between those two is where false greens live.
 Benchmarks · June 20, 2026 · 16 min read
I gave my coding agent eyes three different ways. Here's the honest scorecard.
Playwright MCP, Chrome DevTools MCP, and Reticle all let an AI coding agent see a running web app. I built Reticle, so I ran a committed benchmark across all three and wrote down where each one wins and where mine loses.
 Workflow · June 18, 2026 · 2 min read
The bottleneck moved, and nobody updated the org chart
Agents research and write code in minutes. Then a human spends two days verifying it. The slow step isn't the code anymore, it's the proof.