On this page
Your agent says the change is done. The tests are green, the summary is confident, and the page looks right. None of that tells you the change works. It tells you the agent stopped.
You are not alone in squinting at that. In Stack Overflow's 2025 survey, the top frustration with AI tools, named by 66% of developers, was "AI solutions that are almost right, but not quite". Almost right is exactly what a green suite cannot tell apart from right.
Both figures in that post are from Stack Overflow's 2026 survey.
AI verification is the step that checks, inside the running application, whether a change an AI agent made produced the outcome it claimed: the request succeeded, the state changed, nothing errored on the way, and the result traces back to the source line that caused it. It turns "done" from a claim into a verdict with evidence.
This guide covers what that step reads, what a verdict has to carry, how it differs from testing, observability and evals, what it cannot do, and how to add it to a project in one commit.
Three ways an agent says "done" and isn't
These are not edge cases. If you build with a coding agent, you have met all three this month.
It fixed the bug and broke the feature
You hand the agent one ticket: the cart total is wrong. It finds the rounding error, fixes it, runs the test for the cart total, and reports success. The test passes. What it did not run is guest checkout, which shares the same price helper and now rounds the other way.
The agent was not careless. It checked what it changed and stopped there, because nothing told it which other flows depend on the same code. A human tester would have clicked through checkout out of habit. The agent has no habits, only the instruction in front of it.
It said it worked, on mock data
You ask for a page that lists a customer's orders. The agent builds the page, wires a fetch, and the list renders with three plausible orders. The summary says the feature is complete and verified.
The three orders are hardcoded. The fetch points at an endpoint that does not exist yet, the error is caught and swallowed, and the component falls back to sample data the agent wrote while scaffolding. Every screenshot of that page looks finished. Nothing that reads the screen can tell the difference.
You are the test suite
The third failure is the one you live inside. Every change the agent makes, you open the app, click through the flow, find the thing it missed, and paste the error back into the chat. Then it fixes that, and you click through again.
That loop works, and it is the slowest step in your whole process. The agent writes a change in minutes and then waits for you to find an afternoon. You did not set out to become the QA function for a model, but without a check the agent can run on its own, that is the job.
Why a green suite is not a verdict
A test is an assertion someone wrote down in advance. It checks that a specific output matches a specific expectation, and it is silent about everything else. A green suite proves the assertions held. It does not prove the change did what was asked.
That gap gets wider when an agent writes both the code and the tests. The test encodes the agent's understanding of the feature, so if the understanding is wrong, the test is wrong in the same direction, and it passes. We wrote about this pattern in using Claude Code for QA automation: the model writing the code is the model grading it.
Here is the mechanism. A typical end-to-end test asserts on what reached the screen: an element exists, a string is visible, a URL changed. The program, meanwhile, made network requests, updated a store, wrote to the console, and maybe fired the same request twice.
None of that is in the assertion, so none of it can fail the test. A green suite written by the agent is a passing grade on a quiz it wrote itself. That is the whole argument of why a green check isn't proof, and it is why AI code verification has to look at what the program did rather than at what a test expected.
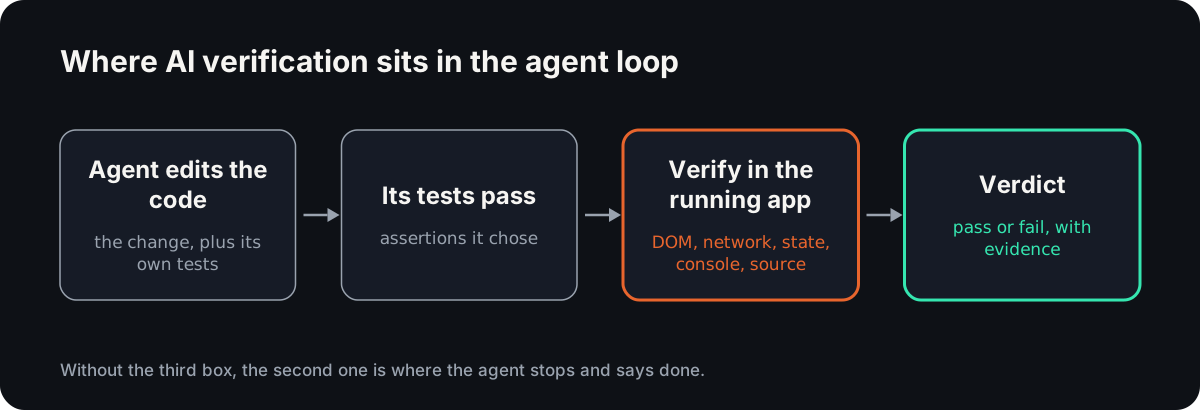
A verdict is a different object. It is derived from what was observed in the running app, it says pass or fail, and it carries the evidence for that answer. You can disagree with a test author. You cannot argue with a captured 500.
What AI verification is, and the five signals a verdict carries
Go back to the definition. Every clause in it is a signal you can read from a running app, and a verdict that skips any of them leaves a class of bug unchecked. These are the five, and the false green each one catches.
1. The DOM outcome. What the user actually sees rendered: the heading, the row in the table, the toast. It is necessary and nowhere near sufficient. It is the only signal a screenshot tool has, which is why screenshot checks pass the mock-data page above.
2. The network result. Every request the action caused, with its status and its count. This is where the swallowed 500 shows up, and where a double-submit shows up as two POST /api/charge requests for one click. Counting requests matters as much as reading their status.
3. The application state. The store, the cache, the record the action was supposed to change. A page can render a total of three items while the store holds four. When the screen and the state disagree, the screen is the one lying, and only a check that reads state can say so.
4. The console. Errors and warnings the app logged while the page kept rendering. A caught exception that falls back to placeholder data usually leaves exactly one trace, and it is here.
5. The source location. The file and line that rendered the failing element or made the failing call. Without it, a failure is a riddle the agent has to solve before it can fix anything. With it, the fix starts in the right file.
Two properties make those signals add up to a verdict rather than a report. First, the verdict is mechanical: it is computed from the observed signals, never from the agent's description of what it did. Second, it is repeatable: the same check against the same build gives the same answer, so a red result means something changed rather than that the checker had a bad day.
That is what it takes to verify AI code honestly. The agent can still write the code, write the tests and describe its work. It just does not get to be the one who decides whether it worked.
Verification versus testing, observability and evals
These four get blurred together because they all produce some kind of "pass". They answer different questions, at different times, from different evidence.
| What it reads | When it runs | What it can conclude | What it cannot | |
|---|---|---|---|---|
| Testing | The assertions someone wrote, against outputs they chose | In CI, before merge | The asserted behaviour still holds | Anything nobody asserted, or whether the assertions match the intent |
| Observability | Logs, metrics and traces from production | After deploy, continuously | Something is wrong for real users, and roughly where | Whether a specific change works before users reach it |
| Evals | Model outputs, scored against a rubric or a judge model | Offline, over a dataset | How often a model's answers are good | Whether one particular change to your app works |
| Verification | DOM, network, state, console and source line from the running app | After every change, inside the agent's loop | This change did or did not produce the outcome it claimed, with evidence | How the page looks pixel for pixel, or behaviour in a browser or app it is not running in |
Evals deserve a note, because they are the closest neighbour. An eval is AI output verification for a model: it grades answers. Code verification grades behaviour. You can have a model that scores well on every eval and still ships a checkout that charges twice.
Reticle implements the verification row. It is an open-source SDK that runs inside your app in development, plus a local server your agent talks to. The agent asks for proof; Reticle drives the flow and reads the five signals above, then returns a pass or fail with the evidence and the file and line.
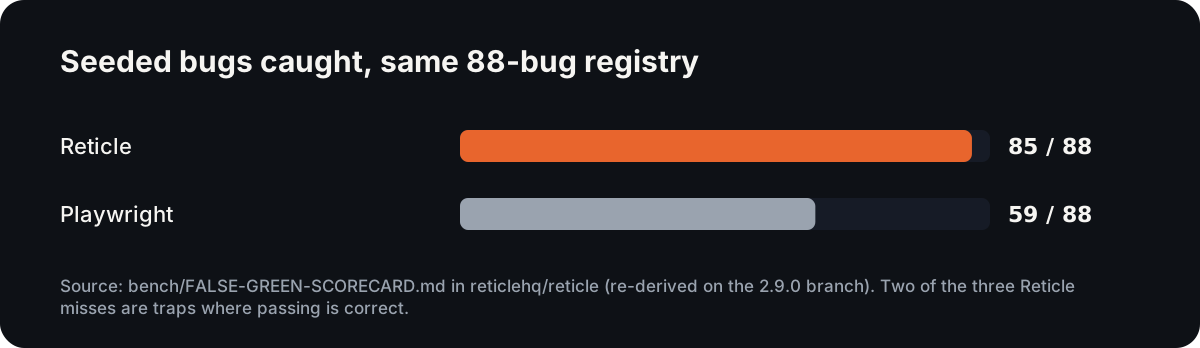
The numbers come from a committed benchmark you can run yourself. Across a registry of 88 seeded bugs that look fine on screen, Reticle catches 85 and Playwright catches 59. Of Reticle's three misses, two are traps where the right answer is to pass, and one is a real miss we count against ourselves.
Once a flow is recorded, re-checking a four-flow suite costs about 480 tokens with no model in the loop, roughly 251 times cheaper than an LLM re-driving the same flows. The same flow replayed eight times returned the same verdict eight times: 0% flake. The full head-to-head, including where Reticle loses, is in the three-tool comparison.
That last property is what makes ai agent verification practical rather than occasional. A check that costs a dollar and ninety seconds gets skipped. A check that costs a fraction of a cent and returns in a second becomes something the agent does every time.
What verification cannot do
Verification reads the program from the inside. That is its strength, and it is also where its limits come from. If you adopt it, adopt it knowing these.
Pixel regressions. Reticle reads computed styles, not pixels. In our own comparison, a stray CSS re-tint that changed 2.3% of the screen was caught by a screenshot diff and missed by Reticle. If the risk you care about is visual, keep a visual regression tool.
Cross-browser rendering. Verification runs in the one engine your app is running in. It will not tell you that a layout breaks in WebKit while Chromium is fine. Playwright runs Chromium, Firefox and WebKit, and that is the right tool for a browser matrix.
State on sites you do not own. Reticle can drive a site you don't own: it runs the page in its own browser, injects its SDK, and reads network, console, DOM and routing. App state and the file:line pointer need the SDK built into your own app, so on a third-party checkout you get what the page did, not its store.
Source lines on Vue and Angular. Reticle works on React, Next.js, Vue, Svelte and Angular, and every one gets the DOM, network, state and console. The file-and-line pointer covers React and Svelte components. On Vue and Angular the agent starts from the failing request instead of the failing line.
Some bugs it has not learned to see. The benchmark miss above is real: stale data inside an iframe. Verification is a set of readers, and a bug that none of them reads can still pass.
Whether you built the right thing. Verification answers "did this change do what it claimed". It does not answer "was that the right thing to build". That second question is validation, and it still needs a person who knows what the user wanted.
How to adopt it in one commit
You do not need a new test framework or a migration. The whole change fits in one commit to an app you already run locally.
1. Install the SDK. From your app's folder:
RETICLE_INSTALL_SOURCE=blog npx @reticlehq/server init
It detects the framework, adds the dev-only connection and registers the local server with your agent. The SDK is stripped from production builds.
2. Tell the agent the rule. One line in your CLAUDE.md or AGENTS.md:
Verify the change with Reticle before reporting it done.
Report the verdict it returns, not your own read of the screen.
3. Let it record a flow. The first time the agent verifies something, say checkout, the flow is saved. From then on it replays on every change with no model in the loop, so the regression you did not ask about gets checked anyway.
4. Add the same check to CI. npx @reticlehq/server verify <url> replays the saved flows against a preview and exits non-zero when one fails, so a broken flow fails the build instead of reaching review.
If you want the history, the team view and preview-by-preview runs without operating any of it yourself, start free on the hosted platform. If you would rather keep everything on your machine, the open-source SDK install guide is the whole product for one developer.
Read next
- What a verification layer is: this step run on every change, the four criteria the term has to meet, and five questions to test any product that claims it.
- Verification vs validation: the older distinction this step builds on, and why agent-written code needs a third question.
- Why a green check isn't proof: the short version of the argument, from before we had a name for it.
- How to use Claude Code for QA automation: a working setup that separates the author from the grader.
- Exploratory testing: what changes when an agent does the exploring, and how a session becomes a regression check.
- AI QA: the three things the term is used for, and which one holds up for a QA team.
- The testing harness: its five parts, and why most harnesses read only what the page renders.
- Agentic testing: the two things the term means, and why testing the agent itself is the one that lasts.
- Testing AI-generated code: the seven ways an agent's change breaks while its tests stay green.
Fun fact
At the 1987 signing of the INF treaty, Ronald Reagan used his favourite Russian proverb on Mikhail Gorbachev one more time: "trust, but verify". Gorbachev cut in with "You repeat that at every meeting", and Reagan answered "I like it". The official transcript records laughter after both lines, so even nuclear arms control has a running gag.
Conclusion
An agent's "done" is a claim about its intent. AI verification turns it into evidence by reading what the running app did: the requests, the state, the console and the line responsible. It will not catch pixel drift or tell you whether you built the right thing, so keep the tools that do.
The next step is small. Install the SDK in one app, add the one-line rule to your agent's instructions, and read the first verdict it returns instead of the summary.
FAQ
What is AI verification?
AI verification checks whether a change an AI agent made produced the outcome it claimed, by reading the running app: what rendered, which requests ran and how they ended, what state changed, what reached the console, and which source line was responsible. The result is a pass or fail verdict with evidence, not the agent's own summary.
How is AI verification different from testing?
A test checks assertions someone wrote in advance, so it is silent about anything nobody asserted. Verification reads what the program actually did after the change, including requests, state and console output a test never looked at. Tests guard known behaviour before release; verification checks each change inside the agent's loop while it works.
Can an AI agent verify its own code?
Not reliably by reading its own work. The agent that wrote the code shares its own blind spots, so its tests and summaries fail in the same direction as the code. It can run an independent check that reads the running app and report that verdict instead. That is how to verify AI code without trusting the author.
Does AI verification replace end-to-end tests?
No. End-to-end suites still gate the release, cover the browsers you support and catch visual regressions verification does not look for. Verification sits earlier, after every edit an agent makes, and catches the silent failures a passing test misses. Most teams that get this right run both and know which question each one answers.
Why Reticle
Your agent says it works. Reticle checks.
- Checks each change inside the running app: network, state and console, not a screenshot.
- Returns a pass or fail with the evidence and the file:line to fix.
- Open-source SDK on your machine, or the platform on every preview and PR.
No credit card required.