On this page
Every project with tests has a test harness, and almost nobody can say what theirs does. It sets up some data, calls some code, compares a value and prints a green line. That vagueness costs something specific: a harness nobody has described is a harness nobody has checked, and the most common thing it fails to check is what the program actually did.
What is a test harness?
A test harness is the code and data that run a test without a person in the loop: it prepares known inputs and stand-ins for missing dependencies, drives the code under test, compares what happened with what was expected, and records the result. It is the scaffold around a test, not the test itself.
That last sentence is why the test harness definition matters in practice: the scaffold decides what a test is able to notice.
The test harness meaning has a narrow and a broad version, and the sources disagree. Wikipedia, following the ISTQB glossary, calls it "a collection of stubs and drivers" and says it "has no knowledge of test suites, test cases or test reports". Most teams use the broad sense, where running and reporting are part of the harness. This guide uses the broad one, because that is the thing you maintain.
The five parts, and what breaks without each
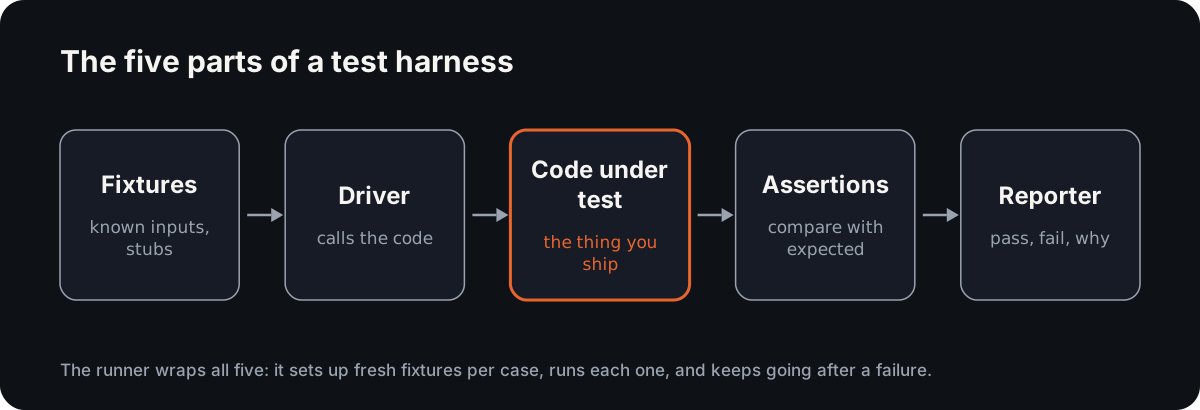
Every working test harness in testing has five parts, whether or not anyone named them. Here is each one and what breaks when it is missing.
| Part | What it does | What breaks when it is missing |
|---|---|---|
| Runner | Finds the cases, runs each one in isolation, keeps going after a failure, sets the exit code. | One failure hides every case after it, and CI cannot tell red from green. |
| Fixtures | Known inputs and stand-ins (stubs, fakes) for things the test should not touch: the payment API, the clock, the database. | Tests pass on Tuesday and fail on Wednesday, because the data or the network changed, not the code. |
| Driver | Calls the code the way a real caller would: a function call, an HTTP request, a click. | You test a shortcut the user never takes, and the real entry point goes unchecked. |
| Assertions | Compare what happened with what should have happened, and fail loudly when they differ. | Everything "passes" because nothing was checked. A test with no assertion is a demo. |
| Reporter | Records which case failed, with what, and why, in a form a person or CI can read. | You know something is red and nobody can say what. |
Fixtures and drivers are the stubs-and-drivers part of the narrow definition. The other three are what turns them into something you can run in CI.
Test harness vs framework vs runner vs suite
These four words get swapped constantly, and the confusion matters when you are deciding what to change.
| Term | What it owns | What it does not own |
|---|---|---|
| Test harness | The whole scaffold for your project: fixtures, drivers, assertions, how it runs and reports. | The library it is built from, or what your tests choose to check. |
| Test framework | A reusable library for writing tests: Jest, pytest, JUnit, Playwright Test. Usually ships a runner and assertion helpers. | Your fixtures, your drivers, and what counts as correct for your product. |
| Test runner | Discovering, scheduling and executing cases, and the exit code. | Setup data, and whether the assertions are any good. |
| Test suite | A named collection of test cases, such as "checkout" or a smoke testing set. | How the cases run. A suite is the content; the harness is the machine it runs in. |
So "we use Jest" names your framework, not your harness. Your harness is Jest plus your fixtures, your mocks, your helpers and the assertions your team actually writes. Two test harnesses on the same framework can catch completely different bugs, which is also why swapping frameworks rarely fixes a harness. Playwright alternatives shows this for four browser runners.
For the frameworks themselves, test automation frameworks compares five of them on what each can assert, and automated testing places both in the wider field.
A minimal harness in 30 lines
Here is a complete harness in plain JavaScript. It runs on Node 18 or later with no dependencies. The code under test, placeOrder, charges a card and returns a confirmation message.
// harness.mjs: a complete test harness in plain Node 18+, no dependencies.
import assert from "node:assert/strict";
import { placeOrder } from "./checkout.mjs";

// Fixtures: known inputs, plus a stub that stands in for the payment API.
const fixtures = () => ({
  api: { calls: [], async charge(amount) { this.calls.push(amount); } },
});

const cases = [
  { name: "one item", cart: [{ price: 20, qty: 1 }], expect: "Order placed: 20.00" },
  { name: "two items", cart: [{ price: 20, qty: 1 }, { price: 5, qty: 2 }], expect: "Order placed: 30.00" },
];

// Runner: every case gets fresh fixtures, and one failure never stops the rest.
let failed = 0;
for (const c of cases) {
  const { api } = fixtures();
  try {
    const message = await placeOrder(c.cart, api); // driver: calls the code the way a user would
    assert.equal(message, c.expect);               // assertion: compares output with the expectation
    console.log(`PASS  ${c.name}`);                 // reporter: one line per case
  } catch (err) {
    failed++;
    console.log(`FAIL  ${c.name}: ${err.message.split("\n")[0]}`);
  }
}
console.log(`${cases.length - failed}/${cases.length} passed`);
process.exitCode = failed ? 1 : 0;
Run it:
node harness.mjs
Show the output
PASS  one item
PASS  two items
2/2 passed
All five parts are there, and the exit code is 0, so CI goes green. Keep that result in mind.
What a harness cannot see
Here is checkout.mjs, the code the harness just passed:
// The code under test: charges the card and returns the confirmation message.
export async function placeOrder(cart, api) {
  const total = cart.reduce((sum, item) => sum + item.price * item.qty, 0);
  await api.charge(total);
  if (cart.length > 1) await api.charge(total); // a retry that should never have shipped
  return `Order placed: ${total.toFixed(2)}`;
}
Every customer with more than one item is charged twice, and the harness reported 2/2. Nothing in it was broken. It asked one question, "is the message right?", and the message was right.
That is the mechanism. An assertion can only compare values the harness holds. This harness holds the return value. The charge happened somewhere else, as a side effect, and nothing recorded it in a place the assertion could read.
The stub in the fixture already counts calls. Add one line that reads it:
assert.equal(api.calls.length, 1, `charged ${api.calls.length} times`);
Show the output
PASS  one item
FAIL  two items: charged 2 times
1/2 passed
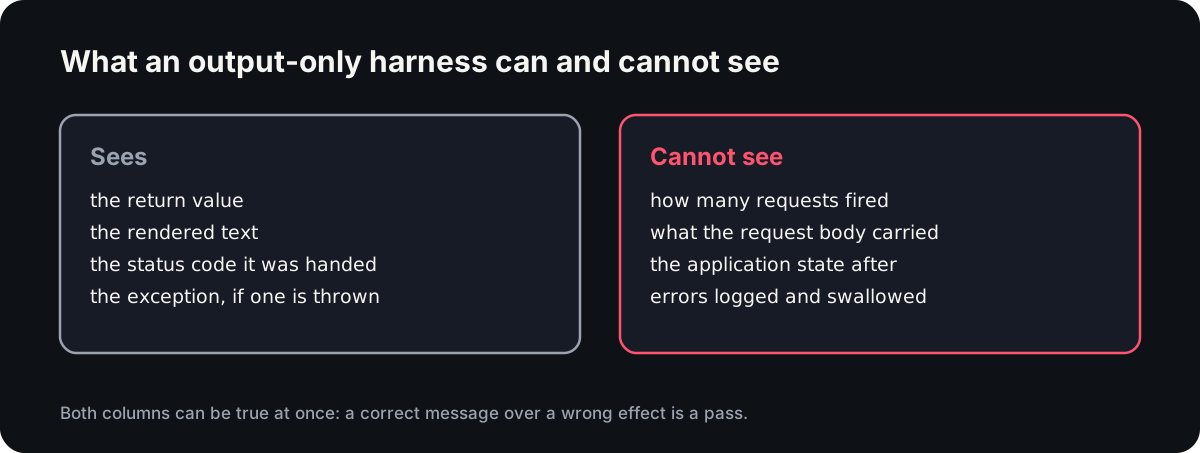
In a web app the blind spot gets wider, because most end-to-end harnesses assert on what the page renders. Three things never reach the DOM:
- The network response. "Order placed" can render while
POST /api/chargereturned 500, or fired twice. - The application's own state. The store can hold the old cart while the page shows the new one.
- The console. An error caught and logged inside a handler leaves the page looking fine.
A harness that reads only rendered output cannot tell a working feature from a convincing one, because a convincing feature produces exactly the same output. The difference lives in the effects, and the effects live where that harness is not looking. This is the gap behind why a green check isn't proof.
Harness design for agent-written code
Coding agents make this blind spot expensive. An agent that writes the feature, the test and the summary optimises for the output looking right, and that is the one thing an output-only harness checks. Three design choices close most of the gap.
Assert on effects, not just output. For every flow, write down the consequence that proves it worked: one POST to the charge endpoint, with the right amount in the body; the order in the store; an empty console; the same state after a reload. Then assert on those. The rendered message becomes one check among several.
Record at the boundaries, inside the app. Effects are only assertable if something captured them: the network layer, the state store, the console. A screenshot records none of the three. Recording inside the running app, in development, means the harness can read what happened instead of inferring it from pixels.
Keep the verdict deterministic. Fixed fixture data, waits on real signals (a request finished, a state changed) rather than sleeps, and no model deciding pass or fail. The same build and the same input should give the same verdict every run. If the verdict can change between two runs of one commit, a red build means "maybe".
This is the harness Reticle provides for web apps. Its SDK runs inside the app in development and records network, state and console, so a flow's checks can assert on effects. An agent drives the flow once, the flow is saved, and npx @reticlehq/server verify http://localhost:3000 replays the saved flows without a model in the loop, exiting non-zero when one fails. We call that step AI verification.
The verification harness tutorial runs that loop end to end on a small app, with the real terminal output.
In the published benchmark it caught 85 of 88 seeded bugs with no false alarms. Two of the other three are traps a correct tool must not flag, and one is a genuine miss, stale data inside an iframe.
Re-verifying a four-flow suite costs about 480 tokens, roughly 251 times cheaper than a model re-driving the same flows (the comparison is with that re-drive, not with a compiled suite, which costs no tokens). Eight replays of one flow gave the same verdict eight times: 0% flake. The scorecard has the method.
A harness that guesses how long the code takes has the same blind spot in time, and that is where most flaky tests come from.
Grade your harness: nine questions
One point per yes.
- Does every case get fresh fixtures, with nothing shared between them?
- Does one failing case leave the others running?
- Does the driver use the same entry point a real user or caller uses?
- Does every test assert on at least one effect, not only on rendered output?
- Can it count requests and read their bodies?
- Can it read the application's state after the action?
- Does an error in the console fail the test?
- Does the same build give the same verdict on every run?
- Does a failure say which case, what was expected, and what happened instead?
Six or more is a harness that catches real bugs. Under four, it mostly confirms that the page renders.
To run effect-level checks on your own app, start free on the hosted platform, or follow the open-source SDK install and keep everything on your machine.
Fun fact
JUnit, the template for a whole family of xUnit test frameworks, was written on a plane. Martin Fowler records that JUnit "was born on a flight from Zurich to the 1997 OOPSLA in Atlanta", pair programmed by Kent Beck and Erich Gamma, test first.
The twist is that Beck's earlier habit, from Smalltalk, was to have each team build its own framework so it controlled its own environment. One of the most reused testing harness designs came from a man who preferred you wrote your own.
Conclusion
A test harness is five parts: a runner, fixtures, a driver, assertions and a reporter. Most harnesses have all five and still verify very little, because their assertions read only what the code returned or rendered. The bugs that cost money, a double charge, a stale store, a swallowed error, live in the effects.
Take the nine questions to your own harness this week. Pick the flow that would hurt most if it broke, and add one assertion on an effect: a request count, a value in state, or a clean console.
FAQ
What is a test harness in software testing?
A test harness is the code and data that run tests automatically: it prepares known inputs and stand-ins for missing dependencies, drives the code under test, compares the result with the expected outcome, and records pass or fail. Strict definitions limit it to stubs and drivers, but most teams include the runner and reporter too.
What is the difference between a test harness and a test framework?
A test framework is a reusable library such as Jest, pytest or JUnit, which supplies a runner and assertion helpers. A harness is your project's whole scaffold built on top of it: your fixtures, mocks, drivers and the assertions your team writes. Two teams on the same framework can have very different harnesses.
What are the components of a test harness?
It has five components: a runner that finds and executes cases, fixtures that provide known inputs and stubs for dependencies, and a driver that calls the code the way a real caller would. Assertions compare what happened with what was expected, and a reporter records which case failed and why, in a form CI can read.
Is a test harness the same as a test suite?
No. A test suite is a collection of test cases, such as all the checkout tests. The harness is the machinery those cases run in: setup, execution, comparison and reporting. The same suite can run in two different harnesses and catch different bugs, because the suite is the content and the harness is the machine.
Why do tests pass when the feature is broken?
Usually because the harness asserts only on output, such as a returned message or rendered text, while the bug is in a side effect: a duplicate request, wrong data in state, or a logged error. The output looks right, so the assertion passes. Asserting on effects as well as output closes most of that gap.
Why Reticle
Your agent says it works. Reticle checks.
- Checks each change inside the running app: network, state and console, not a screenshot.
- Returns a pass or fail with the evidence and the file:line to fix.
- Open-source SDK on your machine, or the platform on every preview and PR.
No credit card required.