On this page
- Where Playwright MCP beats my own tool
- The token cost of looking
- The number that actually compounds: re-running a regression
- Some bugs never reach the DOM at all
- Where it's just a tie (and I should say so)
- So which one should you actually use
- The full scorecard
- The one honest sentence
- The bug that convinced me to build this
- Fun fact
- Conclusion
- FAQ
Fair warning before you read further: I built one of the three tools in this comparison. That makes me biased, so I am not going to ask you to trust my adjectives. Every number below comes from a benchmark harness that is committed to the repo, including the case where my own tool loses to a screenshot. Skip to the full scorecard if you only want the table.
Your coding agent just finished a change. It says "done ✅". You open the browser and the button does nothing.
This happens because the agent never actually saw the running app. It edited code, reasoned about what should happen, and reported success based on the diff.
It is programming with a blindfold on. The model writes plausible code and has no way to check whether the page it just changed behaves the way it claimed. Checking it is the step called AI verification, and this post is about the three tools that can do it today.
There are three real ways to take the blindfold off right now: Playwright MCP, Chrome DevTools MCP and Reticle. All three speak the Model Context Protocol, so any MCP agent (Claude Code, Cursor, OpenCode) can use them:
| Browser drivers, Playwright MCP & Chrome DevTools MCP | In-app instrumentation, Reticle |
|---|---|
| Drive a real browser from the outside. The agent navigates, clicks, takes a screenshot or reads the accessibility tree, and inspects network through the Chrome DevTools Protocol. Works on any URL with zero install. | Embed a dev-only SDK inside your app so the agent reads the program from the inside: store state, the React commit stream, emitted domain events, network cardinality, console, plus the source file:line that rendered an element. Full depth in an app you own; on other sites it injects its SDK and reads network, console and DOM. |
I built Reticle. Below is what happened when I put all three through the same harness. I am going to lead with the cases where Reticle loses, because if you are reading this on r/programming you have already smelled the vendor pitch coming and you deserve the caveats first.
Where Playwright MCP beats my own tool
A screenshot is the actual rendered frame. That gives Playwright and DevTools a category of bug that an in-app tool genuinely cannot see.
Here is the one I measured. I dropped a stray CSS filter: hue-rotate(90deg) saturate(1.6) onto the html element. That re-tints the entire rendered page. It changed 21,393 pixels, about 2.3% of the screen. Every computed-style property Reticle reads (color, backgroundColor, opacity, geometry) stayed byte-for-byte identical, because the filter happens at paint time, after the values Reticle can see.
- CAUGHT, screenshot diff (Playwright / DevTools)
- MISSED, Reticle always-on read (computed style)
- 2.3%, of pixels changed, invisible to Reticle
This is the screenshot's home turf and Playwright wins it cleanly. Reticle only matched the catch when I explicitly drove it through its opt-in reticle_visual_diff (which uses CDP under the hood). The always-on, no-install SDK reads computed style, so anything that only shows up in actual pixels (font-load failures, paint order, GPU and compositing bugs) is a real blind spot.
The other places the browser drivers win outright:
-
Any site, zero cooperation. Playwright and DevTools test a URL you have never touched with nothing injected. When this benchmark ran, Reticle had to be embedded in your app to work at all.
Update, October 2026: Reticle now also drives sites you don't own by injecting its SDK into its own browser; app state and file:line still need the SDK in your build.
-
Trusted native input. Playwright drives real CDP input: native keyboard, mouse, file pickers, drag-and-drop, all with
isTrusted: true. Reticle defaults to synthetic dispatch and real input is opt-in only. -
Cross-browser. Playwright runs WebKit, Firefox, and Chromium. Reticle runs on whatever single engine your app runs on.
-
Browser-level scope. Multi-tab, popups, cross-origin, downloads, auth dialogs, and network mock/intercept all live at the browser level. Reticle is scoped to one page runtime, so it observes network but mocking stays the app's job.
-
Protocol-level debugging. Chrome DevTools MCP speaks raw CDP, so for low-level network and performance traces on any site it is the right tool. Reticle only sees app-level network, so the wire protocol is out of its reach.
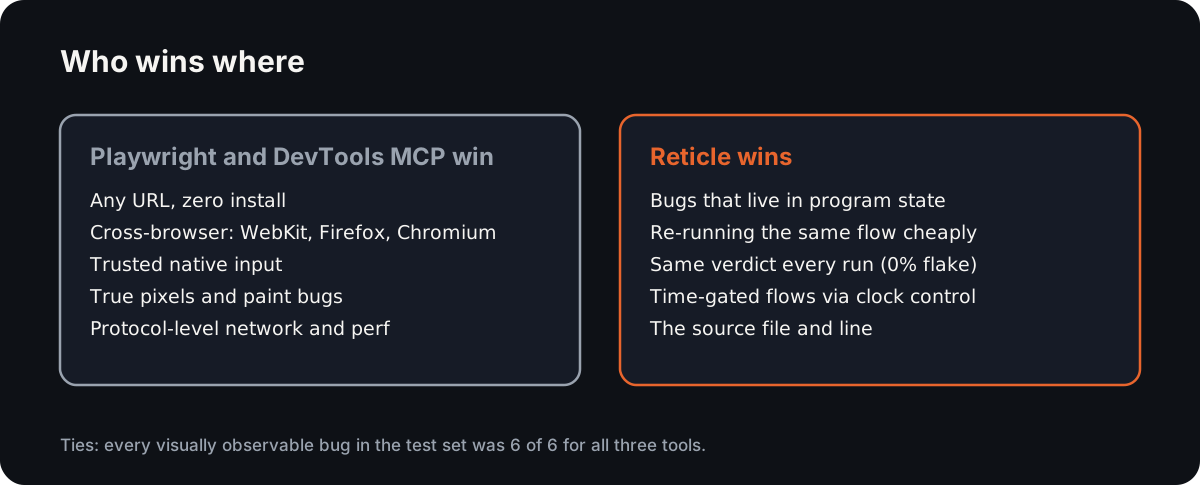
So if you are running a cross-browser release matrix, need trusted native input, or are chasing a pixel-level visual regression, stop reading and use Playwright or DevTools. That is genuinely their job. Reticle is built for a narrower situation: an agent verifying what a flow actually did, deepest in an app you own, on every edit.
The token cost of looking
When a browser-driver agent wants to know what is on the page, the common move is to dump the full accessibility tree (or a screenshot) and let the model read it. That is a lot of tokens for a question as small as "did the modal open".
Reticle asks narrow questions instead. A query plus an observe plus an assert is a few small structured calls.
| Per verify step | Tokens |
|---|---|
| Full accessibility-tree snapshot (e.g. Playwright MCP) | ~7,300 |
| Reticle verify loop (query + observe + assert) | ~100 |
Across a 20-step flow that is roughly 2,000 tokens with Reticle against roughly 146,000 with full-tree snapshots.
Here is the honest asterisk, because this number gets misread. If you force Reticle to also dump the whole accessibility tree, the gap shrinks to about 1.8×. The big multiple comes from Reticle usually not needing the whole tree to answer the question, so most of the saving is architectural rather than a magic compression trick. I would rather you hear that from me than catch it yourself.
The number that actually compounds: re-running a regression
A single verification is interesting. The thing a test suite actually does is run the same verification over and over, on every commit, forever. That repetition is where the gap stops being a percentage and starts being orders of magnitude.
A screenshot or DOM agent has to re-drive the whole flow with the LLM on every single run. The model clicks through, reads the page, and judges the result again, paying full token cost each time. Reticle records the flow once and replays it with no model in the loop: it re-resolves the anchors, advances the clock, and checks the declared consequence.
| Re-verify a known flow | Cost per run | Flake | vs Reticle |
|---|---|---|---|
| Reticle deterministic replay | ~240 tok | 0% | baseline |
| Playwright / DevTools (LLM re-drive) | ~30,000 tok | sampled | ~127× more |
A 4-flow suite (reticle_flow_verify) | ~480 tok, ~60 per added flow | 0% | 251× |
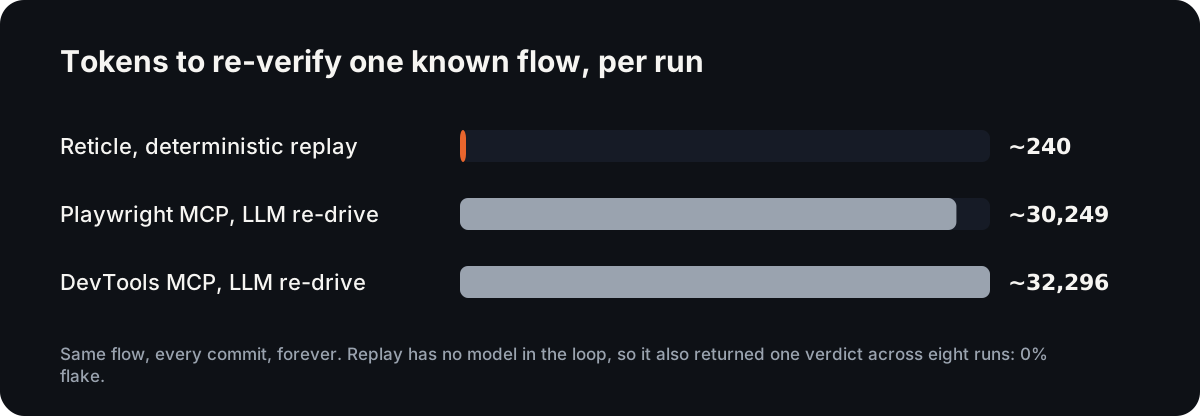
Two things matter here. First, the per-run cost is two orders of magnitude apart and it compounds with every commit.
Second, and I think this is the bigger deal, the flake rate. I replayed the same flow eight times and got one status and one verdict, identical across all eight runs, because there is no LLM sampling temperature or tool ordering to vary.
A browser-driver agent re-drives with a live model every run, so its verdict is sampled rather than fixed. Flakiness is the number one tax on any regression suite, and a model-free replay pays zero of it by construction.
The suite-scale number (365 tokens at 2 flows, 483 at 4) comes from consolidating into one verdict that reports per-flow contradictions and what the run never reached. That costs about 60 tokens a flow, so it grows with suite size but stays far below re-driving every flow.
That is the only place a within-field 100× multiple is physically real. You cannot catch 100× more bugs than exist, but you can re-verify a 4-flow suite 251× cheaper than re-driving it with an LLM.
Some bugs never reach the DOM at all
The DOM is a lossy projection of your program. Plenty of real bugs live in the gap between what the program did and what the page shows. A tool standing outside the browser, looking at pixels or markup, has no way to see them. Reticle sits in the runtime, so it can.
I built a small suite of bugs that look completely fine on screen and measured who caught what:
- UI lies about the store. The displayed count says one thing, the store holds another. A screenshot and a DOM read both report the visible value and have no source of truth to contradict it. Reticle caught 2 of 2; the browser drivers caught 0 of 2.
- Dead handler, green button. A "Ship" button is present, clicks fine, and changes nothing in the store. Reticle declares the success condition as
deployments.0.status == live, so the replay fails when the store never moved, with no element drift to hide behind. - Double-submit. An action that fires its network request twice passes any presence check. A declared
net { count: 1 }consequence catches the second call. Acount: 0rule catches a forbidden call, like a reverted migration endpoint or a stray privacy beacon that should never fire. - Silent console error. The action logs a
console.errorand the page still renders. Aconsole { absent: true }consequence fails on it, read after the action settles so it cannot pass before the error fires. - Wasted-render storm. A React component thrashing at 108 commits per second while producing identical output. There is no DOM mutation, so an outside tool sees an idle page. Reticle reads the commit rate off the devtools hook (108 vs a healthy 36) for about 50 tokens.
- Blast radius. An action corrupts an unrelated piece of store state for a view that is not even on screen. Nothing visible changes anywhere. This is the deepest one, and no out-of-page tool can see it because the damage lives entirely in program state.
I want to be precise about the honest boundary here, because "Reticle sees state" can sound like more than it is. Raw network counting and raw console capture are parity: Playwright has route and page.on('console'), DevTools reads both too.
The advantage is not that Reticle can observe these. It is that the count or the clean console is a declared, deterministic consequence of a replayed flow, checked after settle, that cannot be faked by a locator that healed onto the wrong element.
The genuinely Reticle-only catches are the ones that require reading the store: the UI-vs-store desync, the dead-handler oracle, the blast radius, and the render storm.
There is also a time dimension. Reticle controls the app's setTimeout and Date, so a flow gated on a 2.6-second transition (a deploy going from "building" to "live") verifies in about 202 milliseconds by freezing and advancing the clock. The browser drivers are perfectly capable of testing this, but they have to sleep through real time and guess the duration.
Under-wait and the test goes flaky. That gap scales with the timer: a 5-minute timeout makes it roughly 1000×.
Where it's just a tie (and I should say so)
Marketing pages love to imply total dominance. The honest reality is that a large slice of web bugs are things a human can see on screen, and any tool with a JavaScript evaluate can reach those.
Every visually-observable bug I tested (computed style, geometry, occlusion, color, theme, six bugs in total) came back 6 of 6 for all three tools. Reticle is more ergonomic there because it is one native call instead of authoring a JS snippet (roughly 117 to 259 fewer tokens per check), but it is not more capable. A tie is a tie.
In a live gpt-4o tool-use loop over five broken-app scenarios, using authoritative model usage tokens rather than a proxy:
- 5 / 5, Reticle (~55k tokens)
- 4 / 5, Playwright MCP (~30k)
- 3 / 5, Chrome DevTools MCP (~32k)
Reticle caught the most, but it spent about 1.7× the tokens to do it on this particular run. That is the trade in a single fresh detection loop. The token advantage I keep talking about only shows up once you start re-running the same flow. One model, one turn budget, five scenarios is a small sample, so treat the accuracy ordering as directional rather than gospel.
So which one should you actually use
Pick by what you are actually doing. Ignore which vendor wrote the blog. Running both is a reasonable split: Reticle for the inner build-verify loop, Playwright for the cross-browser release gate. The agent-side setup for that split is in using Claude Code for QA automation.
| Your situation | Reach for | Why |
|---|---|---|
| Agent building a React or Next app you own, verifying each edit | Reticle | In-loop, ~100 tok per check, sees program state and the source file:line, refuses risky clicks |
| Regression suite you re-run on every commit or in CI | Reticle | Deterministic replay: 0% flake, ~240–480 tok per run, ~127–251× cheaper than re-driving with an LLM |
| Bug whose truth is in state (UI-vs-store desync, double-submit, side-effects) | Reticle | No out-of-page tool can see these; they live in the program |
| Testing a third-party site with zero setup, or across browsers | Playwright | Nothing injected, any engine. Reticle can now drive third-party sites too, but reads app state and file:line only in your own build |
| Cross-browser matrix across WebKit, Firefox, Chromium | Playwright | Reticle runs on whatever single engine your app runs on |
| Trusted native input: file pickers, drag-drop, real keyboard | Playwright | Reticle defaults to synthetic dispatch; real input is opt-in only |
| Pixel or paint visual regression: font-load, paint order, GPU | Playwright | A screenshot is the rendered frame; Reticle only reads computed style |
| Protocol-level network or perf debugging on any site | DevTools | DevTools MCP speaks raw CDP; Reticle observes app-level network |
The rule of thumb I keep landing on: if you own the app and an agent is building it, Reticle is the cheap, deterministic, state-aware inner loop, and the regression suite that does not go flaky. If you are driving someone else's site, many engines, real input, or true pixels, that is Playwright and DevTools territory.
The full scorecard
One table, wins and ties and losses stated plainly. Every row comes from a committed harness in the repo, and you can reproduce it with pnpm bench. The same harness later took a very different driver, a small decision model, in the Jev benchmark.
| Dimension | Reticle | Playwright MCP | DevTools MCP |
|---|---|---|---|
| Scripted regression detection (10 bugs) | 10 / 10 | 9 / 10 | 9 / 10 |
| Live agent loop, 5 broken scenarios | 5 / 5 (~55k) | 4 / 5 (~30k) | 3 / 5 (~32k) |
| Cost to re-verify a known flow | ~240 tok, 0% flake | ~30,249 (LLM re-drive) | ~32,296 |
| Re-verify a 4-flow suite, per run | ~480 tok (251×) | K × ~30,249 | K × ~32,296 |
| Visual / computed-style / theme bugs (6) | 6 / 6 | 6 / 6 | 6 / 6 |
| Pixel / paint regression (CSS re-tint) | MISSED (driven: caught) | CAUGHT | CAUGHT |
| UI-vs-store desync (2) | 2 / 2 | 0 / 2 | 0 / 2 |
| Wasted-render storm | Detected (~50 tok) | no signal | no signal |
| Time-gated flow (2.6s transition) | ~202 ms (clock control) | real wait ≥2,600 ms | real wait ≥2,600 ms |
| Source localization (component + file:line) | stack 4/4, source 4/4 | CSS selector only | CSS selector only |
| Third-party site, no install | yes since Oct 2026, SDK injected (no app state or file:line) | yes | yes |
| Cross-browser (WebKit / Firefox) | no | yes | Chromium only |
| Trusted native input | opt-in CDP only | yes | yes |
The caveats, stated up front. The token numbers use an OpenAI BPE proxy (
o200k), which is within about ±20% of Anthropic text tokens, except the live agent loop which uses authoritative model usage. That loop is one model (gpt-4o), one turn budget, and five scenarios, so the accuracy ordering could shift on a bigger sample. The competitor results were corrected for apparatus artifacts (an MCP init timeout, a nav-badge mismatch, a result-parsing bug) before reporting. And three Reticle bugs got fixed while building this benchmark, which is exactly what a benchmark is supposed to surface.
The one honest sentence
If you want the whole thing compressed: Reticle ties on anything a person can see in the DOM (with a real and growing cost advantage on re-runs), and it wins where the bug requires seeing the program itself, its state and the same flow replayed deterministically. Playwright and DevTools win on true pixels, any-site reach, real input, and cross-browser.
It is not that one of these is better and the rest are obsolete. They are aimed at different moments. A browser driver is the right tool when you want nothing injected, in any engine. An in-app layer is the right tool when an agent is building an app and needs to check its own work cheaply on every edit, then re-check it forever without flaking.
I built Reticle because that second moment, the agent's inner loop, did not have a tool that read program truth instead of guessing from pixels. The benchmark above is my attempt to show exactly where that bet pays off and exactly where it does not. Every harness behind these numbers is open source, so if you find a case where they do not hold, clone it and show me.
See it on your own app in one line. Reticle's SDK is open source, dev-only and localhost-only, and none of your app's data leaves the machine (the CLI sends anonymous usage counts;
reticle telemetry disableturns them off). Paste one line into your agent and it sets itself up. Star the Perception SDK on GitHub ★
The bug that convinced me to build this
One afternoon sums the whole project up. (The actual origin involves a wasted Claude Code quota and a hackathon: how Reticle started.) My agent built a checkout button, clicked it during its own testing, saw a success toast appear, and reported the feature done. The toast was real. The payment request fired twice.
Nothing on screen was wrong. The DOM was correct, the toast was correct, a screenshot would have looked perfect, and an accessibility-tree dump would have passed. The bug lived entirely in the fact that one network call happened a second time. The only way to catch it was to count the request, and the only way to count it reliably on every future commit was to make "fires exactly once" a declared rule that replays without a model second-guessing it.
That double-submit is now scenario one in the benchmark. The lesson I took from it: the bugs that survive an agent's own review are usually the ones that never make it to the rendered page. If your tool can only see what a screenshot sees, those are the exact bugs it will keep waving through.
Fun fact
Playwright was built by the same people who built Puppeteer. The team created Puppeteer at Google and then moved to Microsoft, where they started Playwright: "We are the same team that originally built Puppeteer at Google", as they told InfoQ in 2020. Nobody has said the name was a pun, but the career path does go from puppets to plays.
Conclusion
The three tools look at different things. Playwright MCP and Chrome DevTools MCP stand outside the browser and see what was rendered, on any site and, with Playwright, in any engine. Reticle sits inside the app (built in for your own app, injected on a site you don't own) and sees what the program did, then replays the same flow for about 240 tokens with no model in the loop.
So pick by situation, not by vendor. If an agent is building your app, try an in-app check on the next change it reports as done. If you are testing across browsers or down to the pixel, use Playwright.
FAQ
What is Playwright MCP?
Playwright MCP is a Model Context Protocol server that lets a coding agent drive a real browser from the outside. The agent navigates, clicks, takes screenshots or reads the accessibility tree, and it works on any URL with zero install. Playwright itself runs WebKit, Firefox and Chromium, which covers the cross-browser case.
Playwright MCP vs Chrome DevTools MCP: which should I use?
Use Playwright MCP for cross-browser runs and trusted native input, and Chrome DevTools MCP for protocol-level network and performance debugging. Both drive a browser from outside and both work on any URL. In this benchmark they tied on visual bugs, and Playwright caught 4 of 5 live scenarios to DevTools' 3.
Can a coding agent test its own changes with Playwright MCP?
Yes, a coding agent can test its own changes with Playwright MCP by driving the page and reading a screenshot or the accessibility tree. The catch: a full tree snapshot is about 7,300 tokens per step, and bugs that live only in program state, like a UI that disagrees with its store, never reach the page.
Is a regression suite cheaper with deterministic replay?
Yes. In this benchmark, re-verifying a known flow by replay cost about 240 tokens with 0% flake, against about 30,249 tokens when an LLM re-drove it through Playwright MCP. The saving comes from having no model in the loop, so the verdict is fixed on every run instead of sampled.
Why Reticle
Your agent says it works. Reticle checks.
- Checks each change inside the running app: network, state and console, not a screenshot.
- Returns a pass or fail with the evidence and the file:line to fix.
- Open-source SDK on your machine, or the platform on every preview and PR.
No credit card required.