On this page
Every origin story has a noble version and a true version. The noble version of Reticle is that we identified a structural gap in the agentic development loop. The true version is that I had 50% of my Claude Code quota left, the weekly reset was coming, and I did not want to waste it.
It was late. I was tired. Somewhere between those two facts, a plan formed that I still consider the laziest thing I have ever done professionally: type the goal, hit enter, go to sleep, and let the agent work the night shift. Tokens do not get drowsy. I do.
So I described the product, set the goal, and went to bed feeling like a manager who had just delegated brilliantly.
The morning after
I woke up and made coffee before opening the laptop, which in hindsight was the last good decision in this sequence.
Everything was built. Files everywhere, commits stacked up, a confident summary at the end explaining what had been accomplished. And almost none of it did what I meant.
The business logic technically existed and technically pointed the wrong way. The UX was not bad so much as absent, like someone had described a user flow to a person who had never used a computer. The design was, I want to be fair here, pathetic.
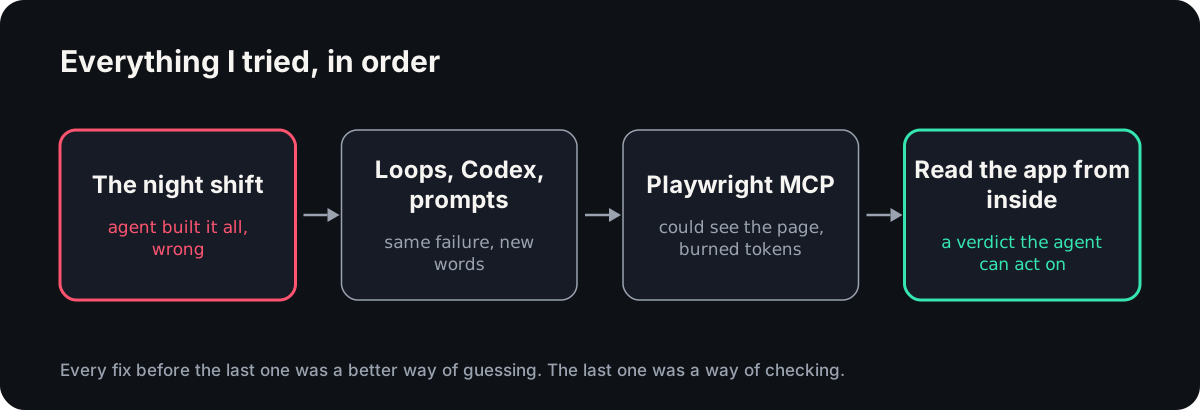
The agent had not failed by any measure it could see. It wrote code. The code compiled. It reported success. It just had no way to know that the thing it built was not the thing I wanted, because it never once looked at the running app.
That is the part that stuck with me while I sat there doing the arithmetic on a night's worth of burned tokens. It was not a bad model. It was a model working blindfolded, and I had been the one holding the blindfold on by not being awake to check.
Turns out I was not alone in this. The 2025 Stack Overflow survey found that 66% of developers name AI answers that are "almost right, but not quite" as their top frustration, and 45% say "debugging AI-generated code is more time-consuming".
Almost right is the worst possible failure mode. Broken code announces itself. Almost right waits.
Phase two: doing whatever the internet told me
I did what anyone does at this stage, which is describe the problem publicly and collect diagnoses from strangers.
"You didn't use a loop, that's why." "Try Codex." "Skill issue."
Reader, I implemented all three. I built the loop. I tried Codex.
I accepted the skill issue and rewrote my prompts like a person writing a legal contract against himself, closing every loophole I could imagine the model crawling through.
Same result. Different vocabulary, same class of failure. The agent would still finish, still declare victory, and still be wrong in a way that only showed up when a human opened the browser and clicked a button.
At some point the pattern became impossible to un-see: none of the fixes touched the actual problem. Loops, models, and prompts are all upstream. Every one of them is a better way of guessing. The gap was that nobody was checking.
There is a study I keep coming back to on this. METR ran a randomized trial with experienced open-source developers on their own repos. The developers predicted AI would make them 24% faster. After finishing, they reported it had made them about 20% faster. Measured, they were 19% slower.
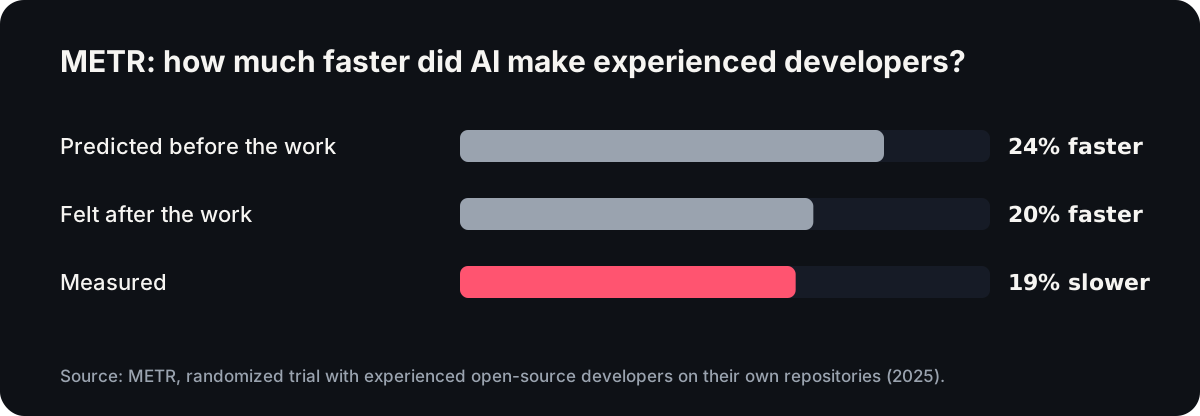
The perception gap is roughly 40 points wide, and it survives direct contact with reality. If humans cannot feel this gap in their own work, an agent grading its own homework has no chance.
Playwright MCP, and the most expensive good idea I had
The next thing I tried actually worked, sort of.
I wired up Playwright MCP so the agent could drive a real browser. Suddenly it could see the page, and results got noticeably better. Things that would have shipped broken got caught. For about a day I thought the problem was solved.
Then I looked at the token consumption.
Screenshots and DOM dumps are enormous. Every glance at the page cost a small fortune in context, and the agent needed a lot of glances. It would burn thousands of tokens rendering a picture of a page to answer a question the page itself already knew the answer to.
Worse, plenty of things still broke, because a screenshot tells you what the page looks like, not what it did. A button can look perfect and fire the wrong request. The DOM cannot see your store, your events, or your network calls. (I later measured all of this properly, losses included, in the three-tool comparison.)
So: right instinct, wrong layer. The agent did not need eyes bolted onto the outside of the browser. It needed to read the app from the inside.
The hackathon where I was supposed to be doing something else
The next day was Entrepreneur's Hack, where the entry requirement was, memorably, to build a company in one day. Not a demo. A company.
I went in with a different idea and started doing customer interviews, which is what you do at these things. Somewhere in the third conversation I mentioned my night-shift disaster as a joke, expecting a laugh, and instead got a very specific groan of recognition.
Then again in the fourth. Then the fifth person described my exact morning back to me using their own project's details.
The pattern was everywhere and nobody had a fix. Everybody's agent was fast. Everybody's verification was a human, manually, later, badly.
DORA's 2025 report puts AI adoption at 90% with about 30% of developers reporting little to no trust in what it produces. That is not a tooling gap, that is a proof gap. We had scaled generation by orders of magnitude and left verification exactly where it was: attached to a person, running at human speed, in a browser tab.
Humans had become the bottleneck in a system explicitly designed to remove bottlenecks.
I told my hackmates we were dropping our idea and building this one instead. This is a rude thing to do several hours into a one-day hackathon and I am grateful they said yes.
We kept validating while we built, and it was the first time I stopped thinking of this as my personal embarrassment and started thinking of it as a product.
Building the thing
What we shipped by the end of the day was crude and worked: verification that runs against the real, running app, drives it like a user, reads what actually happened inside it, and hands the agent back a verdict it can act on without a human in the path.
After the hack I spent weeks doing the unglamorous half: killing bugs, cutting token usage down from the Playwright-era numbers, and tightening the signal until it stopped reporting noise.
The feature I did not expect to matter most is this one. Because it reads the app from the inside, it catches things you never thought to check. Not "your assertion failed" but "this click fired the same request four times and you never asked me about that."
The best verification finds the bug you were not looking for. That is the part I would not have designed on purpose. It fell out of reading the app instead of photographing it.
From Iris to Reticle
At the hackathon I named it Iris. Eye, iris, seeing, very clever, thank you.
Then I searched for it. Iris is a flower, a Greek goddess, a messaging protocol, a scanning company, a Pixar short, and a long list of startups. I was not going to rank for my own product's name in this decade.
Naming your company something that already means eleven things is a self-inflicted wound that keeps bleeding forever.
So Iris became Reticle. A reticle is the crosshair in a scope: the thing you look through to aim precisely. Better meaning, better story, and available.
The branding worked, and I have become insufferable about telling other founders to open a search tab before they open a domain registrar.
What the night actually taught me
I did not set out to build a company. I set out to avoid staying up late, and got handed a very expensive lesson at 7am about what agents cannot do.
The lesson was not "agents are unreliable." Agents are wonderful. The lesson was that a system with a fast generator and a slow verifier is not fast, it is just faster at producing work that still needs to be checked. Every hour I spent improving the agent made the pile of unverified work grow.
The loop only closes when the proof runs as fast as the code.
That is the whole product. It came from laziness, a wasted quota, and being too stubborn to accept "skill issue" as a diagnosis. The step it automates now has a name, AI verification.
I still delegate my night shift to the agent. The difference is that now something is awake, watching it, and willing to say no.
Sources: 2025 Stack Overflow Developer Survey: AI, METR: Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity, DORA 2025 report.
Fun fact
Perl's official glossary lists laziness as "the first great virtue of a programmer", defined as "the quality that makes you go to great effort to reduce overall energy expenditure" (perlglossary). Impatience and hubris are virtues two and three. So falling asleep and leaving an agent running wasn't a character flaw. It was scripture.
Conclusion
Reticle came from one night of letting a Claude Code agent work unsupervised and one morning of finding out what it built. Better loops, models and prompts did not fix it, and Playwright MCP helped but cost too much and still could not see what the app did. What fixed it was reading the running app from the inside.
If your agent works while you sleep, give it something that checks the work before you wake up. The step has a name, and the AI verification guide shows how to add it.
FAQ
Can I leave Claude Code running overnight?
You can leave Claude Code running overnight, but expect it to finish and report success whether or not the result is what you meant. In this story it built everything and almost none of it worked, because it never looked at the running app. Give it a check that reads the app before you trust the summary.
Why does an AI agent say the work is done when it is not?
An AI agent says the work is done because, by every measure it can see, it is: the code was written, it compiled and nothing errored. It has no way to know the result is not what you wanted unless something checks the running app. Better prompts, loops and models do not change that.
Does Playwright MCP fix AI agent verification?
Playwright MCP partly fixes AI agent verification: it lets the agent see the page, and results improve. The costs are tokens, since screenshots and DOM dumps are large, and blind spots, since a screenshot shows what the page looks like rather than which requests fired or what the store holds.
Do AI coding tools make developers faster?
AI coding tools do not always make developers faster. In METR's randomized trial, experienced open-source developers predicted AI would make them 24% faster, felt about 20% faster afterwards, and were measured 19% slower. The gap between how fast it feels and how fast it is survives direct contact with reality.
Why Reticle
Your agent says it works. Reticle checks.
- Checks each change inside the running app: network, state and console, not a screenshot.
- Returns a pass or fail with the evidence and the file:line to fix.
- Open-source SDK on your machine, or the platform on every preview and PR.
No credit card required.