On this page
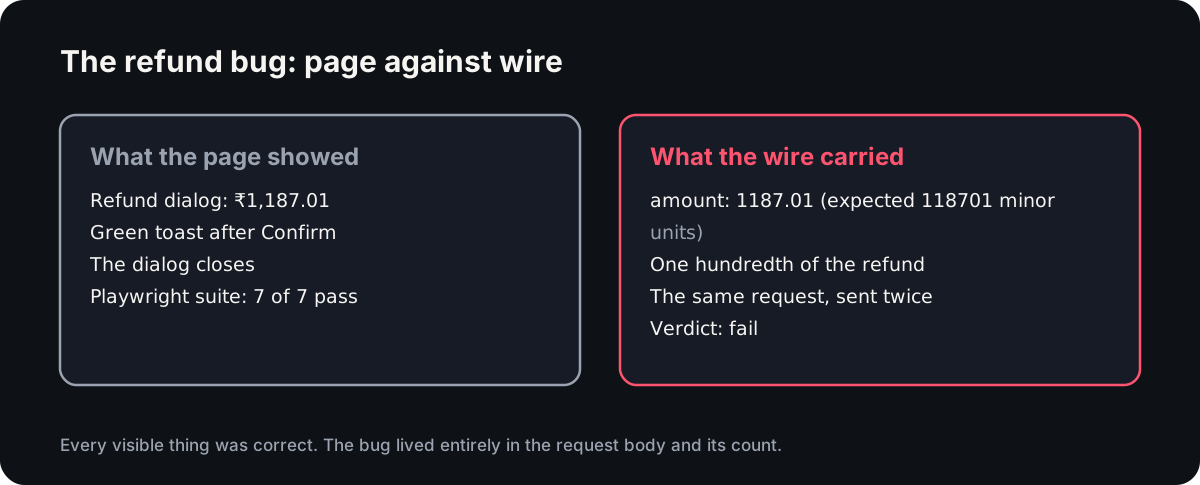
A refund dialog on a payments dashboard reads ₹1,187.01.
The agent clicks Confirm. A green toast appears. The dialog closes. Every visible thing is correct.
The POST body underneath carries amount: 1187.01. The real value is 118701 minor units. The customer is getting back one hundredth of their money, and the same click sends the request twice.
The repository's own Playwright suite passes 7 of 7 over that screen.
It is not a bad suite. It asserts the toast appears, and the toast appears. It asserts the amount renders, and the amount renders.
The bug lives in the gap between what the page showed and what the wire carried, and no DOM assertion reaches into that gap. Reaching into it is what AI verification is for.
We found it with a model that cannot write a sentence, for six tenths of a cent.
The week Jev broke containment
TypeSafe AI shipped Jev on 15 September. It does not generate text. You hand it a state and typed questions, and it answers all of them in one pass as a choice from a set you defined, with a probability attached.
Input costs $0.042 per million tokens. Output is free, because there is no output to bill.
Within days people were not discussing it, they were shipping on it: it became the fastest-adopted model on Vercel's gateway this year.
Read those three bullets. A fresh action space every step, the DOM as the state, a small language model kept only for typing. That is our architecture, built by somebody else, in the same week.
By day three somebody had built the product we sell.
We gave it the wheel
Reticle is an SDK you embed inside your own web app. From inside the program it reads store state, network calls, domain events and the console, which is how a body carrying 1187.01 gets caught while the screen says ₹1,187.01.
The harness is the loop that drives your app when no agent is driving it. It picks what to touch next and says what it expects to happen. It does not decide whether anything worked. (For the general term, the parts of any test harness and what they can and cannot see are in their own guide.)
Every candidate action is built in our code, from the accessibility snapshot:
act:e5      click the button "Issue refund"
fill:f1     fill the textbox "Amount"
act:f3      click the button "Confirm"
finish      stop driving, the app has been covered
look_again  look again without acting, this reading looks wrong
Jev returns one key. It cannot name an element that is not on the page, because the only names in play were read off the page a second ago.
A driver that cannot invent a selector cannot hallucinate one.
The best statement of that principle is not ours. It is rule four of six in a thread read a third of a million times:
never let it invent options
build the candidate list in code, from the DOM, the retriever, the tool trace, then let it pick
The receipt
A real Razorpay Blade dashboard. Same persona, same 250-step budget, same tool surface. The only thing that changes between the two runs is which model does the driving. It is one run per arm and the raw output is not published yet, so read this as a field report you cannot check, not a benchmark.
| frontier driver | jev | |
|---|---|---|
| Wall clock | ~7 min | under 2 min |
| Cost | $2.1233 | $0.006210 |
| Token volume | 8,048,739 | 161,331 |
| Actions driven | 47 | 39 |
| Actions proved | 2 | 12 |
| Flows saved | 12 | 1 |
| Found the 100x refund bug | yes | yes |
342x cheaper. Around 50x fewer tokens. 8x faster per decision, ~340ms against ~2,809ms.
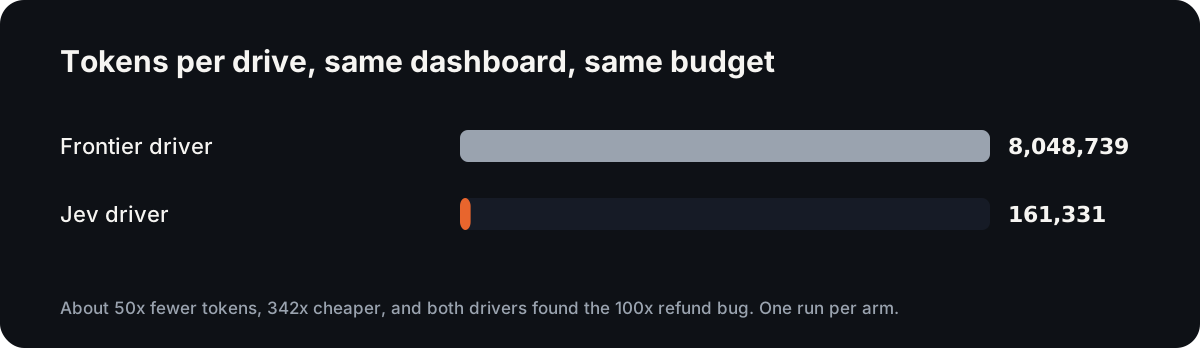
And a tie on the only row that decides whether the rest matters.
Both drivers found the money bug. Changing the model moved the cost by two and a half orders of magnitude and moved the finding by nothing.
That is the whole thesis, paid for: the engine finds the defect, the model only drives.
One run per arm, on one app. Read the ratios as a direction. Which workloads that result generalises to, and which it does not, is the subject of the Jev playbook.
Where it lost
Flows saved: 12 against 1.
A saved flow replays forever with no model in it, so it is the real product of a drive. The frontier driver names and segments journeys as it goes. A model that cannot emit a string cannot name anything, so ours keeps one long recording and carves it up badly.
If you want a regression suite rather than a bug hunt, take the expensive driver today.
The proved column is unfair in the other direction. 12 against 2 looks like a rout, but our driver declares an expected consequence on every action by construction while the frontier driver does it inconsistently. 43 of its 47 actions came back undecided. That is a design difference, not intelligence.
What we learned
The cheap model was never the risk. Both fixes that got Jev working were bugs in our driver. Its first version declared no consequences at all, so every verdict came back as nothing-was-proved while the run reported itself a fast success. Its second version declared consequences that were unconditionally true. The model did exactly what it was asked both times.
Confidence is not evidence. Picture an agent asking Jev what to do on a message composer. It can choose Send at 0.95 probability, and the page can still show no observable effect. A type-valid, high confidence decision, and nothing happened. (The same trap applies to grading, covered in Jev vs LLM-as-judge.)
So the verdict stays out of reach. Our engine decides what happened from evidence, with no model in it. A System One model cannot hallucinate a type, but it still returns a probability, and a probability is not proof.
Miscalibration costs coverage, not correctness. An independent study puts Jev's out-of-distribution ECE at 0.107 against a 0.024 noise floor. That matters enormously if you threshold on confidence. It barely touches us: if Jev picks the wrong element, we click the wrong button and waste a step. It cannot produce a false green, because it is never asked whether anything worked.
The ceiling is the context window. 32K. Our state was around 17,000 characters. A large enough DOM does not degrade the drive, it fails the call.
Netscape was fast too
Here is the part nobody in the timeline is saying.
Jev is a genuine breakthrough. It is also a young company selling one product, at a price with no margin in it, in a category four trillion-dollar companies can enter on a Tuesday.
Output tokens are free. That is a wonderful thing for us and a terrifying thing for them, because free is not a moat, it is a dare.
Search is the closest live comparison. Building something better than the incumbent has not, so far, been enough to take the incumbent's market, and the incumbent can copy the feature far faster than the challenger can copy the distribution.
Being right and being early has not been enough. It rarely is.
The Netscape pattern is older and blunter. Invent the category, watch the incumbent bundle a free copy with the thing everybody already has, disappear.
For Jev the bundle move is obvious. Any frontier lab can add a typed-decision endpoint to an API developers already hold a key for, price it at zero, and the switching cost becomes the only thing keeping anyone on a separate vendor with a separate waitlist.
I hope that does not happen. I am not betting a product on it not happening.
Which is the actual reason our driver is one of two behind a stable interface, and why the verdict was never going to come from a model we do not control. If TypeSafe is acquired, deprecated or price-hiked in eighteen months, we change one file. The thing you are paying us for does not move.
That is not a prediction about Jev. It is what taking a dependency on a very young company should look like.
What we do next
Score before choosing. Our candidate cap is 40 and it is the weakest number in the file. A cheap scoring pass that ranks candidates by relevance to the goal would beat our document-order truncation.
Fix the naming problem. One long recording against twelve named journeys is the gap that matters. The likely answer is a small generating model kept only for naming, which is what Browser Use does for typing.
Get off presence grade. Most of our evidence is the weakest tier that still counts. Moving it to consequence grade needs the drive to learn the app's own signal and endpoint vocabulary first.
Run it on your app, not ours. One dashboard is not a result. The 32K ceiling is the thing we most need somebody else's DOM to tell us about.
Run it yourself
Free, and it takes about two minutes.
- Go to app.reticle.sh and sign in.
- Create an API key.
- Put it in your project's
.env:
RETICLE_CLOUD_KEY=rk_live_your_key_here
Then point it at a preview or dev environment, never production, because it really does click things:
RETICLE_INSTALL_SOURCE=blog npx @reticlehq/server init
npx @reticlehq/server verify http://localhost:3000 \
  --persona "a support agent issuing a partial refund, then checking the balance"
We hold the model credentials and proxy the call, so that key is the only secret on your machine and you never sign up to TypeSafe at all.
Run both drivers on your own app. If the cheap one proves less than the expensive one on your codebase, that is the result worth sending us. For how the same harness compares with Playwright MCP and Chrome DevTools MCP as the driver, see the three-tool comparison.
I built Reticle, so discount the adjectives. Two of the three failures above were bugs in my own driver, the run is n=1, and the raw JSON is gitignored. Re-run it before you believe any of it, including the parts that flatter us.
Fun fact
NASA lost the Mars Climate Orbiter in 1999 to a unit mix-up. Ground software reported thruster impulse in pound-seconds where the interface spec required newton-seconds, so navigation was off by a factor of 4.45 and the orbit's lowest point came out at 57 km, too low to survive (Mishap Investigation Board report). The refund bug in this post was off by a factor of 100. It only cost money, not a spacecraft.
Conclusion
Jev drove our verification harness for $0.006210 against $2.1233 and found the same 100x under-refund the frontier driver found, on a screen a Playwright suite passed 7 of 7. The cost moved by orders of magnitude and the finding did not. It also saved one flow to the frontier driver's twelve, so today it is a bug hunter, not a suite builder.
This is one run on one app. Run both drivers on yours, and send us the case where the cheap one proves less.
FAQ
What is a verification harness?
A verification harness is the loop that drives your app when no agent is driving it: it picks what to touch next and says what it expects to happen. It does not decide whether anything worked. A deterministic engine reads the store, network calls, domain events and console, and decides that from evidence, with no model in it.
Why did the Playwright suite miss the refund bug?
The Playwright suite missed the refund bug because it asserted on the page, and the page was correct. The toast appeared and the amount rendered, so it passed 7 of 7. The bug lived in the POST body, which carried one hundredth of the real amount and went out twice.
How much cheaper was Jev than a frontier driver in the benchmark?
In this benchmark Jev was 342x cheaper than a frontier driver: $0.006210 against $2.1233 for one drive of the same payments dashboard, with about 50x fewer tokens and around 340ms per decision against 2,809ms. Both found the 100x refund bug. It is one run per arm, so read the ratios as a direction.
Can a model like Jev decide whether a test passed?
No. Jev returns a probability over options, and a probability is not evidence that an action worked. It can choose Send at 0.95 probability while the page shows no effect, because the message never left. In our harness the model only picks what to try next, so a wrong pick wastes a step instead of producing a false green.
Why Reticle
Your agent says it works. Reticle checks.
- Checks each change inside the running app: network, state and console, not a screenshot.
- Returns a pass or fail with the evidence and the file:line to fix.
- Open-source SDK on your machine, or the platform on every preview and PR.
No credit card required.