On this page
- The table
- Move it: picking the next action
- Move it: routing, gating, filtering
- Move it: classification at volume
- Move it carefully: compaction
- Depends: rubric grading
- Keep: anything that must produce a string
- Keep: open-ended reasoning
- Never: deciding whether something worked
- The thresholds nobody set for you
- Related
- Fun fact
- Conclusion
- FAQ
A week in, the question about Jev has stopped being "is it fast" and started being "which of my calls should it take".
This is the answer we arrived at, workload by workload, with the number behind each one. Some of the numbers are ours, from runs written up in our benchmark post. The rest link to where they were published. Launch week also produced plenty of numbers in posts we could not link back to, and those are left out.
The table
| Workload | Verdict | The number |
|---|---|---|
| Picking the next UI action | Move it | ~340ms per decision against ~2,809ms, on our dashboard drive |
| Model routing | Move it | a cheap decision in front of an expensive one, by construction |
| Gating a tool call before it runs | Move it | a cheap check in front of a dangerous call, by construction |
| Classification at volume | Move it | 5 to 18x faster safety classification (Vercel) |
| Relevance filtering before a choice | Move it | Choice tops out at 255 options, so dense pages need a cut |
| Context compaction | Move it, carefully | it scores the calls you pass it, not what they returned |
| Rubric grading | Depends | 91.5% agreement at $160/M against $33,000 (via Langfuse) |
| Anything that must produce a string | Keep | our driver saved 1 flow where a frontier driver named 12 |
| Open-ended reasoning | Keep | 67.8% against Sol's 74.1% on TypeSafe's own aggregate |
| Deciding whether something worked | Never | a probability about the choice, not about the outcome |
| Anything on a very large DOM | Careful | 32K for state plus the longest question, and it is a cliff |
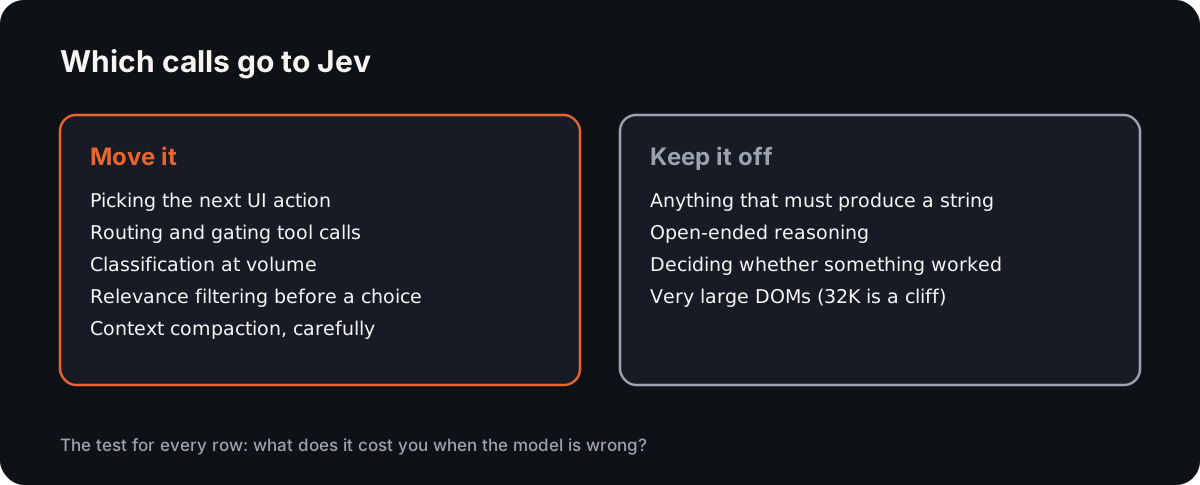
The rest of this is the reasoning, and the parts where our own data disagrees with the enthusiasm.
Move it: picking the next action
This is the best fit anyone has found, and several people found it in the same week.
Several teams put it inside browser agents in launch week. We put it in Reticle's verification harness and drove a real payments dashboard.
Our numbers (full write-up), one run per arm, same app and same loop with only the driver changed:
| frontier driver | jev | |
|---|---|---|
| Cost | $2.1233 | $0.006210 |
| Wall clock | ~7 min | under 2 min |
| Per decision | ~2,809ms | ~340ms |
| Found the bug | yes | yes |
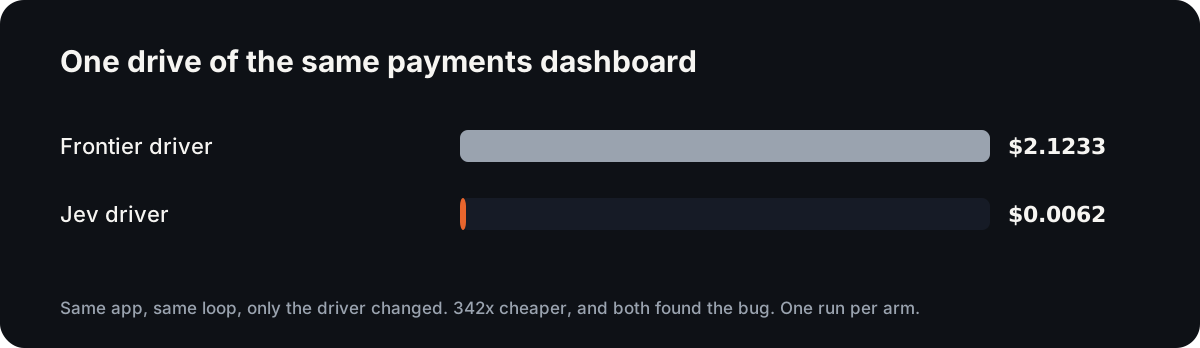
342x cheaper and the same finding. The reason it fits so well is structural rather than economic: the decision is already a selection from a set the page defines, so a model that can only select is not giving anything up.
Move it: routing, gating, filtering
Three variants of the same shape, all cheap decisions standing in front of expensive ones.
Routing sends the easy request to the cheap model and the hard one to the frontier model. Gating checks a dangerous tool call before it executes. The pattern in one line: act automatically above a confidence threshold, and send everything below it to a person.
Filtering is the one people miss. A cheap Score pass ranks every candidate action by relevance, then Choice runs over the shortlist. Choice tops out at 255 options anyway, so on a dense page you need this. We do not do it yet, and it is the biggest single improvement available to our driver.
Move it: classification at volume
The clearest wins in launch week were boring high-volume labelling jobs.
Vercel swapped Jev into a safety classifier that checks whether its agents' commands are safe to run, and that step got five to 18 times faster.
The economics come from one place: Jev prices the state, not the questions. Seven questions cost 1.029x the input tokens of one against an identical state, measured on our own (Jev scorecard). So ask every question you might want, including the ones you will discard.
Move it carefully: compaction
Scoring every tool call and dropping the irrelevant ones, instead of asking a language model to summarise the transcript, is a cheap way to shrink a long agent session before a frontier model reads it.
The caveat: if you pass Jev the tool calls without their outputs, that is all it sees. So it is scoring the shape of what happened rather than the content, and whether that is good enough is workload-specific. Combined with the 32K window, long sessions have to be chunked.
Depends: rubric grading
Good Start Labs graded 6,003 rubric checks, as Langfuse reports, and Jev matched Claude Fable 5.1's verdict 91.5% of the time at $160 per million answers, against $33,000 for Fable itself. DeepSeek V4.1 Flash agreed 93.5% of the time for $260.
Those are strong numbers for a grading job, and we wrote a whole post on where they stop being strong. The short version: nobody has broken down the 8.5% disagreement, and it almost certainly concentrates in the hard cases, which are the ones you built the eval to catch. You also lose the rationale, so a wrong grade is silent.
Grade everything with Jev, re-grade the disagreements with a frontier model when you need to know why. That hybrid is cheap and it keeps the explanation where you actually need it.
Keep: anything that must produce a string
This is where our own result argues against the enthusiasm, so it gets the space.
On the same drive that came in 342x cheaper, the Jev arm saved one replayable flow. The frontier arm saved twelve. A saved flow is the whole product of a drive, because it replays forever with no model in it.
The cause is not intelligence, it is vocabulary. A frontier driver names and segments journeys as it goes. A model that cannot emit a string cannot name anything, so ours keeps one long recording and carves it up crudely. The obvious fix is to keep a small language model around purely for typing.
If your workload ends in a name, a summary, a coupon code or a JSON body, that part stays with a generating model. Plan for two models, not one.
Keep: open-ended reasoning
On TypeSafe's own aggregate workflow test, as Kingy reports, Jev scores 67.8% against Sol's 74.1%, and on invoice processing 61.8% against 79.1%. It is not a universally better model. It is a much cheaper decision at competitive accuracy on the tasks that are actually selections.
Worth being precise about "cannot hallucinate" too, because it is a claim about types and not about correctness. A review at Kingy put it best: Jev can return department = billing with a perfectly valid probability distribution when the right answer is technical.
Never: deciding whether something worked
Picture a browser agent on a message composer. Jev can choose Send with a probability of 0.95, and the page can still show no observable effect, because the message never left. Neither the probability nor the confidence says the website accepted the action.
That is not a flaw. It answered the question it was asked, which was what to do next, and Send was the right thing to do next. Nobody asked whether Send worked, and nothing in its answer could have said.
So in our harness the model picks what to try and a deterministic function decides what happened, from evidence, with no model in it. A System One model cannot hallucinate a type, but it still returns a probability, and a probability is not proof.
The thresholds nobody set for you
If you are gating on confidence, read the independent calibration study before you pick a number. Reproducible for about six cents, and the findings that matter:
- ECE 0.107 against a 0.024 noise floor out of distribution, so 4.4x miscalibrated, while on public benchmarks it is nearly perfect.
- Refit temperature above 1 for choice and score answers, so they are overconfident. The repo's own correction puts it at 1.30 for choices and 1.92 for scores.
- Booleans go the other way, underconfident at T=0.66. The sign of the error differs by question type, so calibrate per question rather than per model.
- 1,051 of 2,000 option probabilities are exactly 0.00. A 1.00 is often saturation rather than certainty.
- Their flat advice: do not use the confidence field. The max probability was never worse and sometimes much better.
Which is survivable if you place the model correctly, and this is the whole point of the table above. Our completion threshold is 0.7 and I am not going to pretend that is a calibrated belief. It is a tuned knob.
If it is wrong, the drive stops early or runs long, and we lose coverage. It cannot produce a false pass, because the model is never asked whether anything passed. That split, a model steering and something else judging, is what AI verification means in a testing agent.
That is the test for any workload on this page. Ask what it costs you when the model is wrong. If the answer is a wasted step, move it. If the answer is a wrong result nobody can see, keep it.
Related
- Which decisions in your testing agent should be Jev calls, for Choice, Score and Noul question design.
- Six things TypeSafe AI's Jev cannot do, for the limits in detail.
- Our measured harness run, including the two bugs in our own driver that made the first version prove nothing.
The harness that produced our numbers is not released. There is a waitlist, and the open-source engine underneath it is free today.
Fun fact
DeepMind's Chinchilla had 70 billion parameters, a quarter of Gopher's 280 billion, and was trained on the same compute budget with four times the data. It "uniformly and significantly" beat Gopher across a large range of tasks (Hoffmann et al., 2022). Gopher was not too small. It was undertrained, which is the most expensive way to be wrong about size.
Conclusion
The short version: it is a selection model, so it wins where the job already is a selection: the next UI action, routing, gating, filtering and labelling at volume. It lags where the work ends in a string, and it should never be the thing that decides whether something worked.
Before you move a call over, ask what it costs you when the model is wrong. A wasted step is fine. A wrong result nobody can see is not.
FAQ
What is Jev from TypeSafe AI?
Jev is TypeSafe AI's System One model: it selects and scores instead of generating text. You give it a state and typed questions, and it returns a choice from options your code defined, with a probability attached. That makes decisions cheap and fast, and it means it cannot produce a name, a summary or a JSON body.
What is Jev good at?
It is good at decisions that already are selections: picking the next UI action, model routing, gating a tool call, relevance filtering and classification at volume. On our payments dashboard drive it was 342x cheaper than a frontier driver and found the same bug, and Vercel reported a safety classifier running five to 18 times faster.
Can Jev be used for model routing?
Yes. Model routing is one of the cleanest fits: a cheap decision sends the easy request to a cheap model and the hard one to a frontier model. Gating works the same way: act automatically above a confidence threshold and send everything below it to a person.
Should I trust Jev's confidence score?
Not as a calibrated number. An independent study measured ECE 0.107 against a 0.024 noise floor out of distribution, with overconfident choice and score answers and underconfident booleans. Its advice is to use the max probability instead of the confidence field, and to treat any threshold as a tuned knob, never as proof.
Why Reticle
Your agent says it works. Reticle checks.
- Checks each change inside the running app: network, state and console, not a screenshot.
- Returns a pass or fail with the evidence and the file:line to fix.
- Open-source SDK on your machine, or the platform on every preview and PR.
No credit card required.